Overview
This project implements a Deep Q-Network and Double DQN agent for LunarLander-v3. Experience replay and target networks help produce stable, consistent landing behaviour.
Why it exists
The work demonstrates how reinforcement learning can solve continuous-control problems in a discrete action space, including decisions around main and side engines.
What I owned
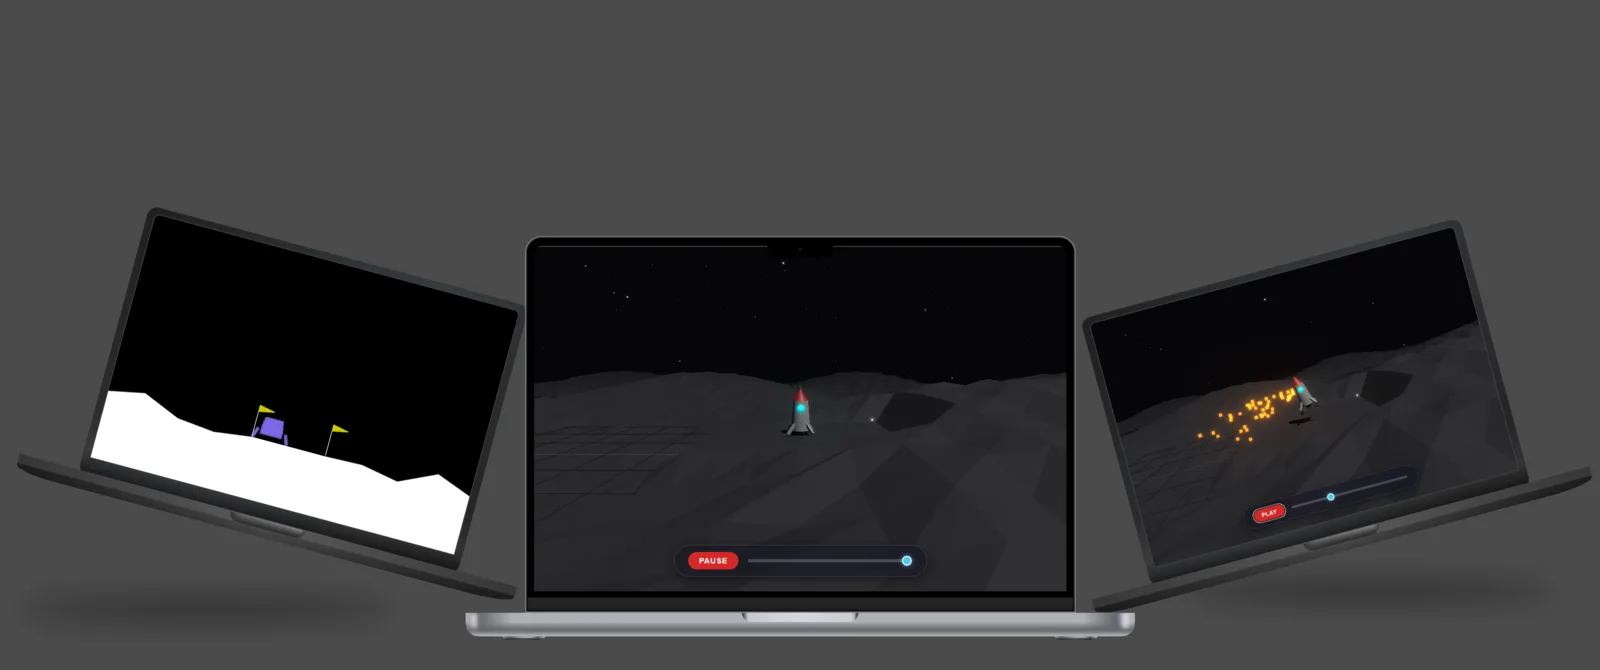
I implemented the PyTorch pipeline, configured experience replay and target networks, achieved an average evaluation reward above 400, and built 2D and 3D browser visualisations for monitoring performance.
Built with
- PyTorch01
- DQN02
- Double DQN03
- Reinforcement learning04
- 3D visualisation05